
Every good AI model needs good data.
If your model has never seen a rare condition, it gets it wrong. We create those images in a controlled 3D environment, with exact labels. Nothing is guessed by AI.
Not a video — a real 3D scene.
Every label you see (bounding box, confidence, segmentation) is generated automatically from the scene itself — the same way we generate labels for your training data.
Not a video — a real 3D scene. Every label you see (bounding box, confidence, segmentation) is generated automatically from the scene itself — the same way we generate labels for your training data.
If your model has never seen a rare condition, it gets it wrong. We create those images in a controlled 3D environment, with exact labels. Nothing is guessed by AI.
You focus on the model. We take care of the data.
0
manual labels
10+
annotation formats supported
100%
reproducible: every image has a known origin
500k+
images generated to date
The data gap
What can’t your model see?
In most computer vision projects, the model isn’t the problem. The missing photos are. The condition is rare, or only happens at certain times of year, or is too dangerous to capture, or hasn’t even happened yet. And no labeling tool, however fast, can label a photo that doesn’t exist.
→ In simulation, each of these gaps becomes a parameter you choose , and you can repeat it as often as you like. See when that helps.
See what you can control.
Pick an area, then a variation. Every scene is built from parameters: objects, materials, lighting, camera, even the label format.
Base scene
Select a variation to see the scene parameters change.
Why simulation
Images you control, not images generated by AI.
Generative models make images that look plausible. Simulation makes images with the content you specified, and labels you can verify.
Images generated by AI
- You don’t know exactly what’s in the dataset
- There’s no scene behind the image, so labels are estimated or done by hand
- Odd details that change from one image to the next
- Cost and time per image are hard to predict
- You can’t repeat a specific scene when you need to
- Class balance is approximate: you get whatever comes out
Controlled simulation
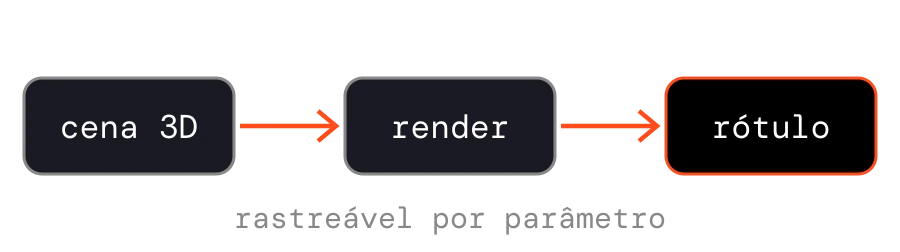
- Every parameter is declared, so you know exactly what’s in the dataset
- Labels come straight from the 3D scene, so they’re exact
- Light, materials and geometry follow physics
- Reproducible: the same scene always generates the same image
- Need a new class, another camera angle or a different label format? We change the scene and regenerate. No new data collection
- You decide how many images of each class you want
Where simulation wins is not realism. It is knowing exactly what is in the dataset and why. We chase realism only as far as the model needs. The goal was never a beautiful render: it is a scene with the right signal for training. A less realistic scene that gets the physics, the scale and the label right is worth more than a beautiful one with mistakes.
// how_we_think_and_operate
Train with synthetic data, validate with real data and refine where it still fails.
We do not defend synthetic data as a principle. For us it is a tool: it helps cover rare cases and gain speed, and your real data remains the final test of the model. That logic is what guides how we think about every project. So besides the images, you get the method: what to generate, how much of it, and how to train with it.
1 · Synthetic training
coverage and rare cases
2 · Real validation
your real data is the final test
3 · Refinement
only what is still missing
↻ new batch in days
The same goes for the way we work. By default, we do not publish client names, data or project numbers: the confidentiality we promise also covers the results, not just the identity. Instead of case studies, we show how we approach each problem and how we measure whether it worked.
How it works
Four steps, from failure to dataset.
Deliverables
In the format your team already uses.
- COCO
- YOLO
- Pascal VOC
- Semantic
- Instance
- Panoptic
- Boxes
- Polygons
- Trajectories
- Spectral bands
Who is on the other side
A person, not a form.
Guilherme Bileki
Founder, SynthVision
Computer vision engineer building production CV systems for agriculture, retail and industry — from diagnosis to dataset.
Quick answers
Common questions.
Does this replace real data?
Usually not, and we’ll say so when that’s the case. Real data stays the final test of your model, and on some projects it’s simply the best training material. Synthetic data comes in to cover what real collection can’t reach, such as rare cases.
In practice: if your real dataset already covers the case well, adding synthetic data may not improve much. The value is in the coverage you’re missing, not in beating a model that’s already good. We’d rather tell you that than sell a dataset that won’t make a difference. The right question is when mixing is worth it, not whether synthetic always wins.
Why not use a big synthetic-data platform or open-source tools?
Use them if they fit your case. They handle the standard 80% well, and a free tool with a capable team is a perfectly good answer.
We step in for the other 20%: the scene, the variation or the label type that no off-the-shelf product offers, and that’s often exactly where your model fails. We can build that part because we built the pipeline ourselves.
What if my team builds its own 3D simulation (in Blender, with help from an LLM)?
That can work, and for some cases it’s a good route. Generating the images keeps getting easier. The hard part is deciding what to generate: how realistic the scene needs to be, which factors to vary, how much synthetic data to mix with real data, and how to check that it actually helped. Those decisions usually take several rounds of trial and error. That’s where we can save you time, whether by delivering the dataset or just reviewing the design of your experiment.
What about models that label on their own (like SAM and VLMs) and AI annotation tools?
Split this into two separate claims, because they hold up differently. “A general model can label your existing real photos faster” — true, and getting truer every quarter. If you already have footage of the condition you care about, an AI-assisted labeling tool is often the faster and cheaper path, and we’ll say so rather than sell you a dataset for something you can already label.
“A general model can run in production instead of a trained one” — true for prototyping and common objects, weaker as you scale: cost and latency per inference at real-time or high volume is a different infrastructure bill than a small trained model, and generalization still lags on your specific SKU, defect or disease.
Neither claim touches the case where the photo was never captured in the first place — a condition too rare, too seasonal, or too dangerous to have shown up in anyone’s footage yet. No labeling tool, however good, can annotate an image that doesn’t exist. That gap is what we generate for, and it’s the reason this doesn’t get smaller as labeling models improve.
How do we start, in practice?
With a diagnostic conversation about your model, not with a data brief. We look at where it fails, what your validation set covers and what’s missing. If simulation makes sense, we start with a small validation batch, so you can judge the quality before committing to the full dataset. If it doesn’t, we’ll say so.
I’m not from a machine learning background. Does it make sense to talk?
Yes. You don’t need to know the technical terms or arrive with everything defined. Just tell us the problem: what the system should recognize and where it gets it wrong. We’ll help turn that into data and explain each step without jargon.
If data is what is holding your model back, let’s talk.
Tell us what your model keeps getting wrong. Together we’ll work out whether simulation is the right path and what it would take.