What we do
Training data for the problem your model keeps getting wrong.
We build 3D training images, labels included, for the situations real-world collection can’t cover: rare cases, hard conditions, and variations you want to control.
When it makes a difference
Real data has limits. These are the four we run into most.
Not every project needs simulation. These are the cases where it usually beats collecting and labeling more real data. In some, the limit is how fast you can label what you already have, and AI-assisted labeling is closing that gap every quarter. In others, the condition was never photographed, and no labeling tool can fix that. That second kind is why simulation stays relevant, however good general-purpose models get.

01 / 04
Rare cases hardly ever show up in the data
Defects, failures and rare conditions show up too rarely in real footage for a model to learn them. In a dataset of 10,000 images, there may be fewer than 50 examples of the problem that matters most. In simulation, we create those examples on purpose, as many as training needs.

02 / 04
Collection can’t keep up with change
Whenever the object, the environment or the task changes, you need new data. Shooting in the field can take weeks, even when labeling is fast, so your training pace ends up tied to field access, not to the model. Simulation separates the two. It helps even alongside AI labeling tools, which also need the photo to exist first.

03 / 04
Label quality is holding your model back
Hand labeling at scale creates inconsistency: masks that don’t follow the object, boxes that differ from one annotator to the next, classes that shift on ambiguous cases. That becomes noise in training, and it’s hard to trace later. AI labeling is improving this for images you already have. In simulation, labels come out exact, straight from the scene, which matters most when you don’t have the images to label at all.

04 / 04
You need test conditions you can repeat
To test a model on “overcast light”, “full shelf” or “partially hidden object” in the real world, you wait for those conditions to happen and hope they repeat. In simulation, each condition is a parameter: you set it, repeat it and compare. It works for any model, whether a small one you trained or a foundation model you only fine-tuned.
What we generate
Dataset types.
Each maps to a computer vision task. Most projects combine more than one.
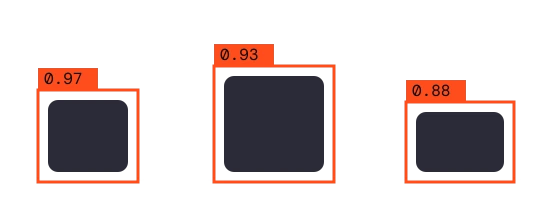
Object detection
Datasets with bounding boxes for finding and locating objects across different lighting, occlusion, scale and viewpoint, including the hard cases and negative examples.
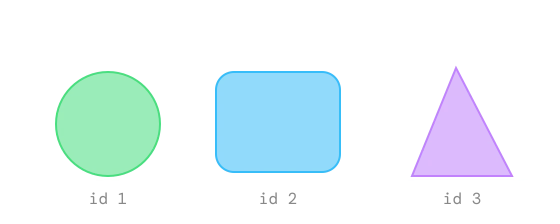
Instance and semantic segmentation
Pixel-level masks computed from the geometry, not traced by hand. Edges are precise and classes are always consistent.
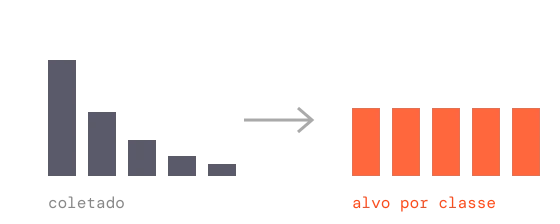
Classification and rare classes (long tail)
Images labeled by category, with the count per class set by you. Top up the rare classes to whatever number you want, instead of accepting the distribution you happened to collect.
Anomaly and defect detection
Procedurally generated defects, with severity, size and position under your control. An anomaly that shows up once in every ten thousand real parts gets a measurable presence in the dataset.
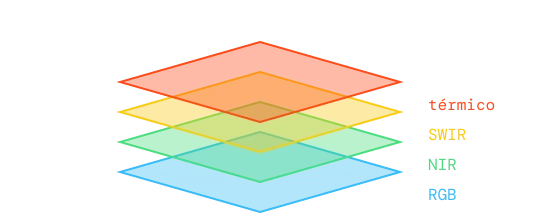
Multispectral and hyperspectral imaging
Custom image channels for spectral analysis, agriculture and remote sensing. We start from a few visual references, so you don’t need a spectral capture campaign.
Camera trajectories (visual odometry)
Simulated camera paths, indoor and outdoor, with camera-motion data (ego-motion) for visual mapping (SLAM) and pose estimation. You control the route, instead of hoping it covers the case.
Evaluation sets and benchmarks
Controlled test sets to validate a model before it goes to production. They work with any model, whether trained from scratch or a foundation model you fine-tuned. They help most on rare, safety-critical cases, where you can’t afford to find the problem in the field.
How it works
From model failure to the training dataset.
Four steps, designed to settle the technical questions at the start, not at delivery.
01
Diagnosis
We start with what your model gets wrong, not with a data request. What’s missing? Under which conditions? What does your validation set really cover, and what doesn’t it?
- Review of current model performance and error analysis
- Definition of the scenarios, the classes and the rare cases
- Agreement on label format, volume and delivery timeline
02
Scene design
Your problem becomes a controlled 3D environment: objects, surfaces, lighting and motion, modeled from your references. This is also where we decide what varies: which parameters change, over what range, and how often.
- Realism matched to what your model needs, not to what looks nicest
- Choosing which factors to vary and over what range, so the model generalizes instead of memorizing the render
- Test images reviewed with you before full generation
03
Generation
The simulation runs at volume. Every label comes from the scene itself and can be traced back to the parameters that produced it, so any image can be explained, reproduced or removed.
- Batch generation at the agreed volume
- Automatic labeling: boxes, masks, polygons, trajectories, spectral bands
- Delivery in the format your team already uses
04
Iteration
You train, and we look at the results together. New errors show up, we adjust the scene parameters, and the next batch targets those gaps, usually within a few days.
- Driven by the errors left in your tests with real data
- The mix of synthetic and real data, and the training plan (blend, pre-train, or just top up the rare classes)
- We finish when the model generalizes, not when the invoice is paid
Engagement models
Three ways to work with us.
They all start the same way: a small validation batch, so you can judge the quality before committing to volume.
Validation first
Feasibility batch
A small dataset aimed at your hardest case. It answers one question: can simulation produce data that improves your model? It’s cheap to run, quick to evaluate, and needs no volume commitment.
Project
Full dataset delivery
Scene build, variation design, generation at volume and labels in your format, followed by tuning rounds based on your real results. This is the typical shape of a first full project.
Ongoing
Data partnership
Does your catalog, your class list or your product line change often? We keep the pipeline running, and each change becomes a regenerated dataset instead of a new collection project.
Start from the model’s error, not from a data request.
Tell us what your model gets wrong. We’ll tell you if simulation is the right answer for it.