About SynthVision
It all started with a project that could not get the data it needed.
This wasn’t a market thesis. A computer vision system was ready to ship, but the data it needed was always months away, every time the product changed.
The origin
A smart fridge that couldn’t see its own products.
The project was a smart refrigeration system. Its job: recognize which products sat on each shelf, in real time, from a camera inside the cabinet. The hardware was ready. The model architecture was solid. The model just had nothing to learn from.
Every product change made the dataset obsolete.Field teams had to photograph the new products in different places, lighting and stock levels. Then the images had to be reviewed, labeled and checked, and only after that could training start.
Updating the catalog, which happened several times a year, took months, from the first photo to a model ready to use. Across a large fleet of refrigerators, that delay was not an annoyance: it was what blocked the launch.
“If I can rebuild this shelf in 3D and swap the products parametrically, I can generate the whole dataset in an afternoon.”
That was the idea, and it held up. The first synthetic dataset matched what weeks of field capture would have produced, and the next product update took a fraction of the time.
SynthVision exists to bring that to any team whose model is limited by data, not by architecture: agriculture, industry, security, retail, logistics, automotive, robotics and research.
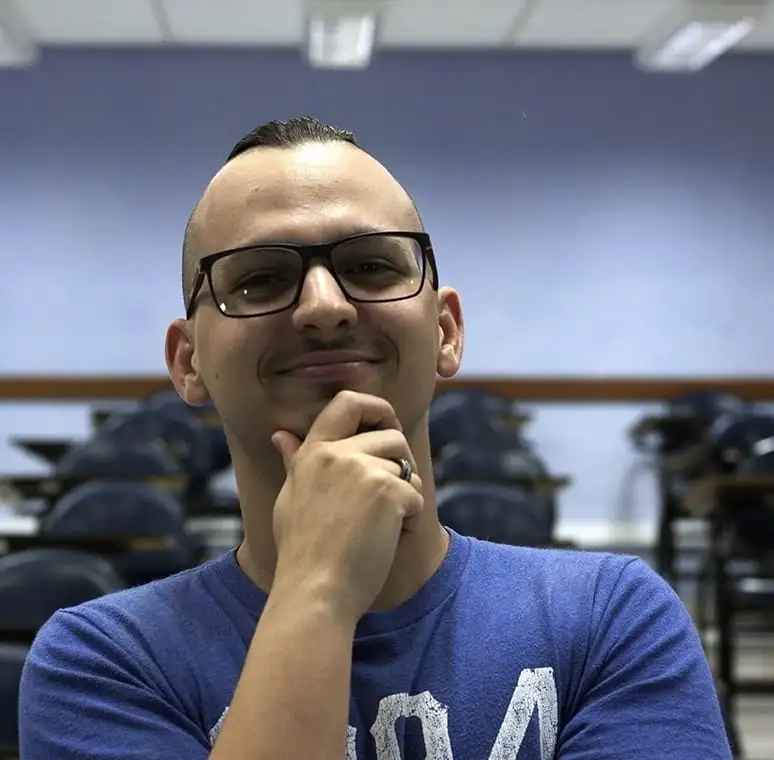
Founder · Computer Vision
Guilherme Bileki
A computer vision engineer who has built CV systems that run in production in agriculture, retail and industry, from smart devices to full machine learning pipelines.
He founded SynthVision after hitting the same wall several times: getting the right training data took longer than building the model. He runs every project end to end, from diagnosis to iterations, so you talk to the person building your pipeline, not a support queue.
Direct access
Sophisticated technology, without the distance of a large supplier.
Large platforms have scale, an ecosystem and plenty of engineers. They also have a limit: if what you need isn’t on their roadmap, the path runs through a support queue, a product team and a release cycle.
Large-company technology.
Direct access to the people who build it.
Here, a request from you becomes a change in the pipeline and then a new dataset. The cycle is short on purpose.
→
→
→
→
How we think
Principles that guide every project.
Some of them make our work harder. We keep them anyway.

Missing data is a model problem
When a model fails in production, the cause is usually a gap in the data: a condition that never showed up, a class with too few examples, a label that was never exact. Fixing that is fixing the model.

Controlled beats generated
When a model generates an image, it isn’t exactly what you specified. When you build a scene, you can describe exactly what’s in each image and how it’s labeled. That difference is the whole product.

Synthetic and real data complement each other
It’s not about swapping one for the other. Synthetic data widens coverage to conditions real collection can’t reach. Real data keeps the model grounded, and it’s still the only honest final test.

Control and traceability are non-negotiable
Every image can be traced back to the parameters that produced it. It’s reproducible, auditable and explainable: not approximately, and not by chance.

A technical partner, not a data vendor
Taking a spec and handing back a zip file doesn’t work, because the right next batch depends on what the model still gets wrong. The tuning loop has to keep running.

Iteration speed compounds
One day between evaluating the model and generating the next batch, instead of two weeks, gives about fifteen times more tuning cycles in the same project window. That’s where the value builds up.

Labeling gets easier. Capturing doesn’t.
General-purpose models keep getting better at labeling images that already exist, and we expect that to continue. It’s real progress, and it solves half the problem. The other half they don’t touch: a condition nobody photographed isn’t in anyone’s dataset, however good the labeling tool. That’s the half we build for, and it doesn’t depend on model size.
Want to see how this applies to your project?
We start with a diagnostic conversation. No presentation and no commitment: just a frank conversation about your data problem.